Local LLM Guides
Best Local AI Video Generators Compared on Quality, Speed and VRAM
Compare local AI video generators on quality, speed and VRAM, with RTX 4090 benchmarks, example clips and an Atomic Chat setup guide.

10/9/26

16 min

Best Uncensored LLMs to Run Locally in 2026
Compare 10 uncensored LLMs to run locally in 2026, including Ollama builds and abliterated models, with setup advice and benchmarks.
10/7/26
15 min

Best Local LLM for Coding in 2026: A Comprehensive Guide
See how the best local LLMs for coding compare across benchmarks, which model we recommend for different use cases, and the key takeaways from our testing.
10/7/26
15 min

Best Local AI Image Generators in 2026: Apps and Models
Compare local AI image generators, with seven models benchmarked on an RTX 5090. See image examples, generation speed, memory use, and license limits.
10/6/26
14 min
10 Best Local LLM Apps in 2026
The 10 best local LLM apps in 2026, compared on interface, platform reach, openness, and tool support — and which one to start with.
10/6/26
12 min

How to use your AI Offline: Run Local LLMs Free
Cloud AI leaks data and goes down. Offline AI runs local LLMs on your own machine. A practical guide to hardware, models, and setup that works.
10/6/26
11 min read
Best Local LLMs for 32GB RAM or VRAM in 2026
The best local LLMs for 32GB of VRAM or RAM in 2026: which quant to pick, exact file sizes, benchmarks, and how much context each model leaves you.
10/6/26
12 min
How to Run Qwen 3.8 27B Locally
Qwen 3.8 27B runs from 12 GB up. Pick the Atomic Dynamic GGUF that fits your hardware, then run it locally with Atomic Chat or llama.cpp. Benchmarks included.
10/6/26
15 min
Best Local LLM for 8GB RAM or VRAM in 2026
Compare local LLMs for 8GB RAM or VRAM, including Qwen 3.5, GLM-4.6V-Flash, Phi-4 Mini and Gemma 3, with model sizes and quantization choices.
10/6/26
12 min
Best Local LLMs for 16GB RAM or VRAM in 2026
The best local LLMs for 16GB of VRAM or RAM in 2026: the quant to pick, file sizes, benchmarks, and how much context each model really leaves you.
10/6/26
12 min
How to Run GLM-5.3-Flash Locally
Explore GLM-5.3-Flash, a 320B MoE with 18B active parameters: local hardware requirements, benchmarks, and available runtime support.
10/5/26
10 min
What Are Abliterated Models? How Refusal Removal Works
What abliterated models are, how refusal removal actually works, how they differ from uncensored and jailbroken models, and how to run one locally.
10/5/26
12 min
How to Run DeepSeek Harness Locally With Atomic Chat
Run DeepSeek Harness on a local model, step by step: Atomic Chat as the OpenAI-compatible provider, plus permissions, plugins, and fixes for the errors we hit.
10/5/26
13 min
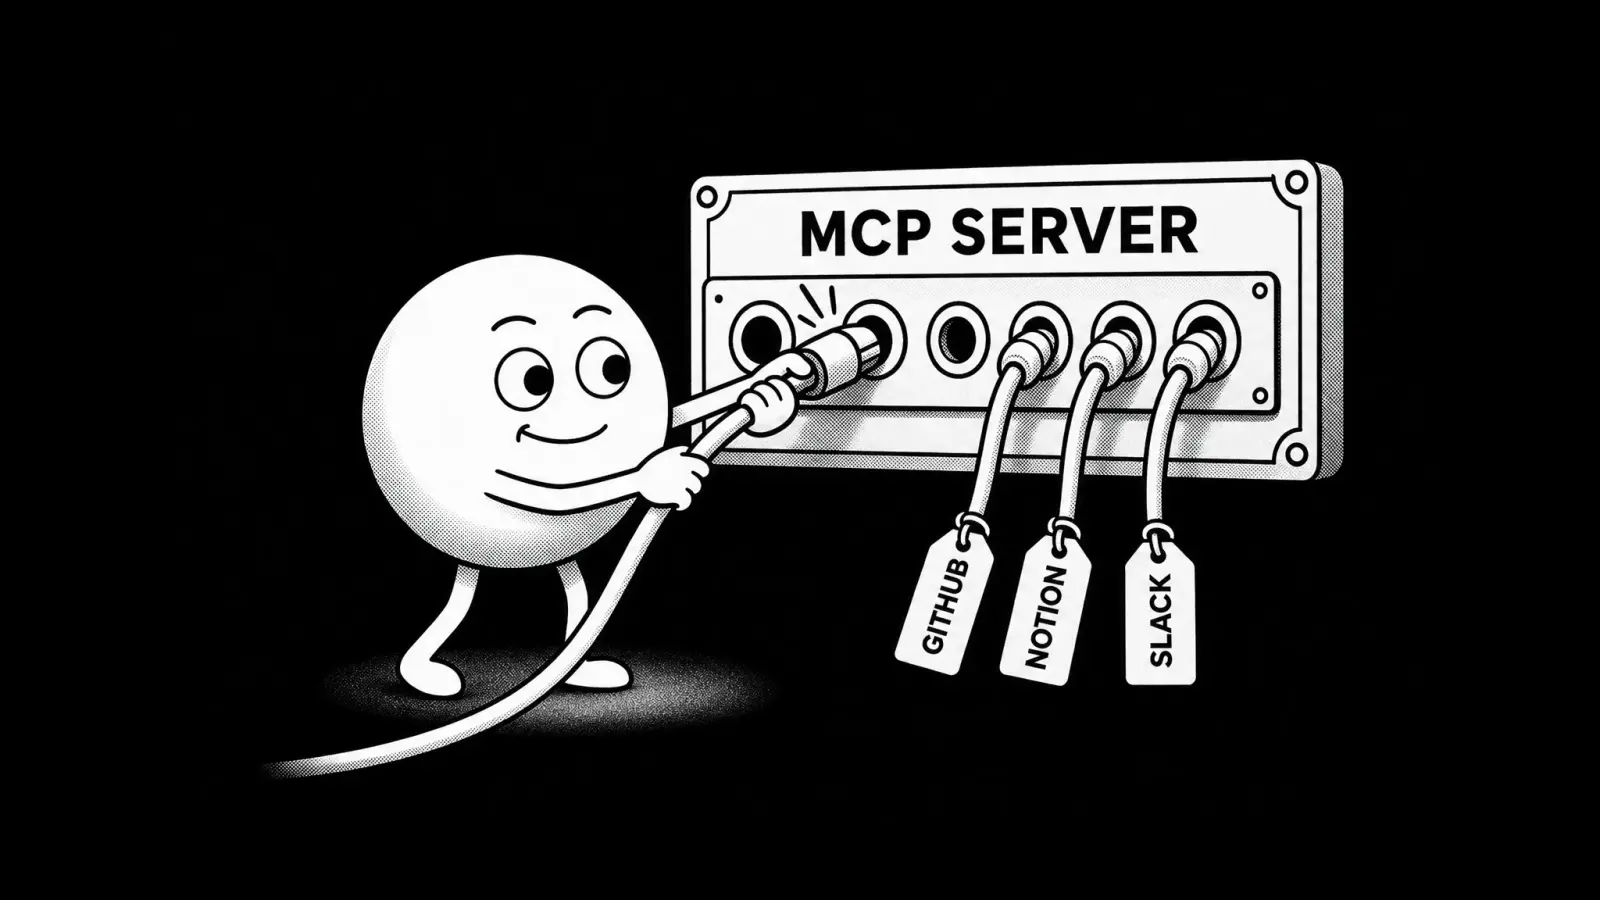
What Is an MCP Server and When Do You Need One?
What an MCP server is, how the Model Context Protocol works, and how to set up, test, and securely use local and remote MCP servers in an AI app.
10/5/26
8 min
How to Run Claude Code Locally: Comprehensive Guide
Step-by-step guide to running Claude Code with a local LLM: install the agent, connect it to Atomic Chat, Ollama, llama.cpp, or LM Studio, and work offline.
10/5/26
12 min
Self-Hosted LLM: Models and Setup Guide
Step-by-step guide to running a self-hosted LLM with Atomic Chat: hardware requirements, the best open models of 2026, and how to expose a local API.
10/5/26
13 min
LLM KV Cache: Guide and Calculator
Learn how LLM KV cache grows with context. Estimate RAM and VRAM with our calculator and explore TurboQuant compression data.
10/5/26
10 min
How to Run DeepSeek V4 Flash Locally
DeepSeek V4 Flash needs 70–162 GB on disk. Pick the Atomic Dynamic GGUF that fits your memory, then run it locally with Atomic Chat or llama.cpp.
10/5/26
15 min
How to Run Ling 3.0 Flash Locally
Run Ling 3.0 Flash on your own machine: hardware requirements, Atomic Dynamic GGUF builds, and setup with Atomic Chat or the TurboQuant llama.cpp build.
10/5/26
10 min

How to Run GLM Locally: A Complete Guide
Run GLM locally with Atomic Chat: pick the right GLM-4.7-Flash or GLM-5.2 build for your hardware, download a GGUF, and chat entirely offline.
10/5/26
9 min
How to Run Qwen Models Locally: A Complete Guide
Learn how to run Qwen locally: pick the right model for your hardware, download the best GGUF quantization, and chat offline using Atomic Chat.
10/5/26
12 min
How to Run Kimi K3 Locally: A Complete Setup Guide
Run Kimi K3 locally: hardware requirements, Atomic Chat setup, renting 8x B300 GPUs on Vast, real costs, and the errors I hit along the way.
10/5/26
14 min
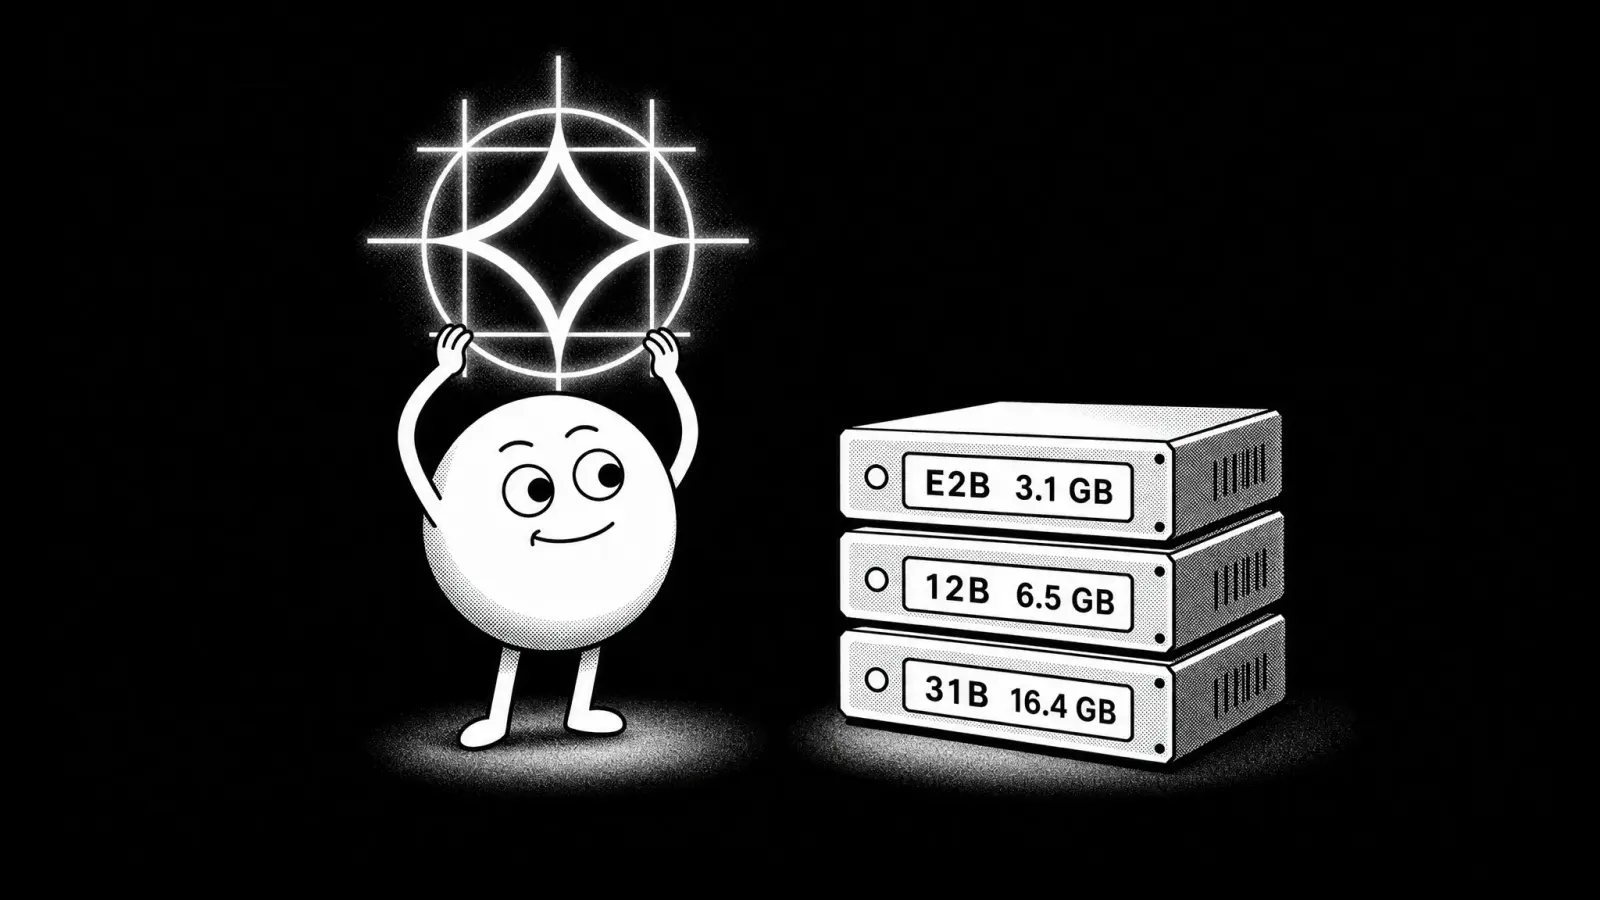
How to Run Gemma 4 Locally: a step-by-step guide
Run Google’s Gemma 4 models on your own machine. Pick the right size for your RAM or VRAM, choose a GGUF quantization, and start chatting locally.
10/5/26
8 min
What Is GGUF? A Complete Guide
Learn about GGUF, the file format for local AI models: how it works, what Q4_K_M means, and how to choose a quantization.
10/5/26
16 min
What Is NVFP4? LLM Quantization Explained
NVFP4 is a 4-bit NVIDIA format for smaller LLMs and faster inference on Blackwell GPUs. Learn how its block scaling and quantization work.
10/5/26
9 min
Is Ollama Safe? Security Audit for Your Local LLM Setup
Is Ollama safe? Review local LLM security risks and learn how to check and harden your Ollama setup.
10/2/26
12 min read

Claude Sonnet 5.5 Alternatives Compared
Compare Claude Sonnet 5.5 with Opus, Fable and GPT-6 Astra, then choose a local Qwen, Ornith or Bonsai model for your hardware.
10/2/26
13 min
Best Local LLMs for RTX 3090: 6 Models Tested
Six local LLM builds tested on RTX 3090: speed, VRAM, context limits and coding demos. Compare exact GGUF files, including ternary Bonsai 2.
10/2/26
18 min
8 Claude Code Alternatives for Local Coding in 2026
Compare eight Claude Code alternatives by local-model support, interface, code access, and approvals. Includes OpenCode, Kilo Code, Codex, and more.
10/2/26
9 min
8 Best Local AI Agents in 2026
Compare the 8 best local AI agents in 2026: Atomic Agent, Kilo Code, OpenClaw, Hermes, Claude Code, Cline, Goose, and pool. See setup and privacy.
10/2/26
18 min
Run Qwen3.8 Flash Next Uncensored Locally
Run Qwen3.8 Flash Next uncensored locally from 80 GB up. Compare the community abliterations, pick the GGUF that fits your memory, then run it in Atomic Chat.
10/2/26
14 min
How to Run Qwen3.8 Flash Next Locally
Qwen3.8 Flash Next runs from 64 GB of RAM up with its n-gram table on SSD. Pick the Atomic Dynamic GGUF that fits, then run it with Atomic Chat or llama.cpp.
10/2/26
14 min
GGUF vs MLX on Mac: Which Format Is Faster
GGUF vs MLX on Mac: why tok/s is a misleading metric, how prefill determines real speed, and benchmarks across 5 runtimes on M1 Max and M5 Max.
10/2/26
12 min read

Best Local LLM for 16GB Mac in 2026
6 local LLMs that fit a 16GB Mac in 2026, with token speeds from public benchmarks, RAM usage, and a short guide to running them.
10/2/26
12 min read
How to Run MiMo-V2.6 9B Locally
Run MiMo-V2.6 9B locally: compare GGUF files, plan RAM and VRAM, and configure llama.cpp. Includes benchmarks and Atomic Chat compatibility.
10/2/26
15 min
How to Run Bonsai 2 27B Locally
Bonsai 2 27B is a ternary GGUF build of the Qwen 3.8 27B language model, from 5.95 GB. Hardware requirements, benchmarks and the llama.cpp fork that runs it.
10/2/26
18 min
Best Local LLMs for RTX 5090: Benchmarks
We measured six local LLMs on a real RTX 5090: tokens per second, VRAM at 32k and 128k, and NVFP4 gains. No estimates from memory bandwidth.
10/2/26
18 min
EXL3 vs GGUF: Quality, Speed and VRAM
EXL3 vs GGUF tested on an RTX 5090: compare quantization quality, prompt speed, token generation, and VRAM, with a working ExLlamaV3 setup.
10/2/26
13 min read
Run Ornith 1.5 Uncensored Locally
Ornith 1.5 uncensored runs from 6 GB up. Compare the community abliterations of the 9B and the 35B, then run one locally with Atomic Chat or llama.cpp.
10/2/26
14 min
Run Qwen 3.8 27B Uncensored Locally
Run Qwen 3.8 27B uncensored locally from 12 GB with a low-bit GGUF. Use Q4_K_M on a 24 GB GPU or 4-bit MLX on a 32 GB Mac.
10/2/26
14 min
How to Run Ornith 1.5 35B Locally
Ornith 1.5 35B runs from a 12 GB GPU up with expert offload. Pick the Atomic Dynamic GGUF that fits, then run it locally with Atomic Chat or llama.cpp.
10/2/26
15 min
How to Run Ornith 1.5 9B Locally
Ornith 1.5 9B runs from 6 GB up, 4 GB text-only. Pick the Atomic Dynamic GGUF that fits your hardware, then run it locally with Atomic Chat or llama.cpp.
10/2/26
14 min

What Is Speculative Decoding?
Learn how speculative decoding accelerates LLM generation by drafting and verifying tokens, and how Atomic Chat uses it.
10/2/26
9 min
How to Run an LLM Locally
Learn how to run an LLM locally on your computer or Mac — pick a model for your hardware, understand quantization, and set it up in a few clicks, for free.
10/2/26
9 min
Ollama vs llama.cpp: Speed and Setup
We benchmarked Ollama and llama.cpp with the same model and hardware. Compare speed, setup, interfaces, and see which local LLM runner fits you.
10/2/26
10 min
How to Run DeepSeek Locally
How to run DeepSeek R1 locally and offline — which distilled sizes fit your hardware, and step-by-step setup with Atomic Chat or Ollama.
10/2/26
10 min

Best Local LLMs for 12GB VRAM in 2026
Eight local LLMs for 12GB VRAM: exact GGUF files, RTX 3080 Ti speed and memory figures, plus Snake and physics tests on an RTX 4070.
10/1/26
15 min

Jev 1.13: Can You Run It Locally? Laya Setup Guide
Can you run Jev 1.13 locally? Learn how it works, see our Jev vs Laya Tetris demo, and set up Laya as an independent local alternative.
10/1/26
12 min
Best Local Embedding Models for RAG: 7 Models Compared
Compare seven local embedding models for RAG by retrieval quality, indexing speed, query latency, memory use, and licensing.
10/1/26
10 min
Best Local LLMs for RTX 4090: 6 Models Benchmarked
Six local LLMs tested on an RTX 4090: generation speed, VRAM at 32k, context limits and coding demos. Compare exact GGUF files for a 24 GB GPU.
10/1/26
14 min
How to Run AI Agents Locally: Models and Setup
How to run AI agents locally for free: the best local models for agentic coding, hardware requirements, and a step-by-step setup guide with Atomic Chat.
9/15/26
11 min
SLM vs LLM Compared on Quality, Speed and Memory
SLM vs LLM compared across nine local model configurations: quality on 74 tasks, generation speed, memory use, and energy for a classification task.
9/14/26
13 min read

LLM Temperature: Examples, Settings and Tests
What does LLM temperature do? Compare 900 model responses, see examples at 0, 0.7 and 1.5, and learn how to choose settings and adjust them in Atomic Chat.
9/9/26
12 min read
GPT-6 Astra Alternatives: Open-Weight and Local Models
GPT-6 Astra benchmarks and open-weight alternatives. Connect your ChatGPT subscription in Atomic Chat, or run Qwen and Laguna on your own hardware.
9/6/26
9 min
How to Run Hermes Agent Locally (via Atomic Chat)
Run Nous Research’s Hermes Agent locally, powered by a local model served through Atomic Chat — no cloud account and no API key. A step-by-step guide.
8/17/26
9 min
How to Run the OpenClaw Agent Locally with Atomic Chat
Run the OpenClaw AI agent locally for free by powering it with a local model served from Atomic Chat — no cloud, no per-token bills, fully private.
8/17/26
8 min
How to Run gpt-oss Locally
Run gpt-oss locally on your own machine. A step-by-step guide to gpt-oss-20b and gpt-oss-120b — the hardware you need and the fastest setup, fully offline.
8/17/26
9 min