Articles by author
GPT-6.1 Terra Alternatives You Can Run Locally
GPT-6.1 Terra specs and benchmarks, plus six open-weight alternatives you can run locally, with GGUF picks for 8 GB to 96 GB of memory.

10/28/26

8 min
How to Run Nemotron 3.5 Bolt E4B Locally: GGUF, Hardware and Benchmarks
Run Nemotron 3.5 Bolt E4B on Linux with an NVIDIA GPU. Check official GGUF benchmarks and memory figures, then use the pinned llama.cpp CUDA setup.
10/23/26
12 min
How to Run Local AI on NVIDIA RTX Spark
Run local AI on NVIDIA RTX Spark with Atomic Chat. Set up local chat, image generation and an OpenAI-compatible API.
10/16/26
4 min
Best Local AI Video Generators Compared on Quality, Speed and VRAM
Compare local AI video generators on quality, speed and VRAM, with RTX 4090 benchmarks, example clips and an Atomic Chat setup guide.
10/9/26
16 min
Best Local LLMs for 12GB VRAM in 2026
Eight local LLMs for 12GB VRAM: exact GGUF files, RTX 3080 Ti speed and memory figures, plus Snake and physics tests on an RTX 4070.
9/30/26
15 min
Claude Sonnet 5.5 Alternatives Compared
Compare Claude Sonnet 5.5 with Opus, Fable and GPT-6 Astra, then choose a local Qwen, Ornith or Bonsai model for your hardware.
9/29/26
13 min
Jev 1.13: Can You Run It Locally? Laya Setup Guide
Can you run Jev 1.13 locally? Learn how it works, see our Jev vs Laya Tetris demo, and set up Laya as an independent local alternative.
9/25/26
12 min
Best Local AI Image Generators in 2026: Apps and Models
Compare local AI image generators, with seven models benchmarked on an RTX 5090. See image examples, generation speed, memory use, and license limits.
9/25/26
14 min
How to Run MiMo-V2.6 9B Locally
Run MiMo-V2.6 9B locally: compare GGUF files, plan RAM and VRAM, and configure llama.cpp. Includes benchmarks and Atomic Chat compatibility.
9/25/26
15 min
Best Local Embedding Models for RAG: 7 Models Compared
Compare seven local embedding models for RAG by retrieval quality, indexing speed, query latency, memory use, and licensing.
9/25/26
10 min
Best Local LLMs for RTX 3090: 6 Models Tested
Six local LLM builds tested on RTX 3090: speed, VRAM, context limits and coding demos. Compare exact GGUF files, including ternary Bonsai 2.
9/21/26
18 min
Best Local LLMs for RTX 4090: 6 Models Benchmarked
Six local LLMs tested on an RTX 4090: generation speed, VRAM at 32k, context limits and coding demos. Compare exact GGUF files for a 24 GB GPU.
9/21/26
14 min
How to Run Bonsai 2 27B Locally
Bonsai 2 27B is a ternary GGUF build of the Qwen 3.8 27B language model, from 5.95 GB. Hardware requirements, benchmarks and the llama.cpp fork that runs it.
9/18/26
18 min
Best Local LLMs for RTX 5090: Benchmarks
We measured six local LLMs on a real RTX 5090: tokens per second, VRAM at 32k and 128k, and NVFP4 gains. No estimates from memory bandwidth.
9/18/26
18 min
8 Claude Code Alternatives for Local Coding in 2026
Compare eight Claude Code alternatives by local-model support, interface, code access, and approvals. Includes OpenCode, Kilo Code, Codex, and more.
9/16/26
9 min
8 Best Local AI Agents in 2026
Compare the 8 best local AI agents in 2026: Atomic Agent, Kilo Code, OpenClaw, Hermes, Claude Code, Cline, Goose, and pool. See setup and privacy.
9/16/26
18 min
SLM vs LLM Compared on Quality, Speed and Memory
SLM vs LLM compared across nine local model configurations: quality on 74 tasks, generation speed, memory use, and energy for a classification task.
9/14/26
13 min read
EXL3 vs GGUF: Quality, Speed and VRAM
EXL3 vs GGUF tested on an RTX 5090: compare quantization quality, prompt speed, token generation, and VRAM, with a working ExLlamaV3 setup.
9/14/26
13 min read
How to Run GLM-5.3-Flash Locally
Explore GLM-5.3-Flash, a 320B MoE with 18B active parameters: local hardware requirements, benchmarks, and available runtime support.
8/28/26
10 min
Best Local LLMs for 32GB RAM or VRAM in 2026
The best local LLMs for 32GB of VRAM or RAM in 2026: which quant to pick, exact file sizes, benchmarks, and how much context each model leaves you.
8/25/26
12 min
What Are Abliterated Models? How Refusal Removal Works
What abliterated models are, how refusal removal actually works, how they differ from uncensored and jailbroken models, and how to run one locally.
8/24/26
12 min
How to Run DeepSeek Harness Locally With Atomic Chat
Run DeepSeek Harness on a local model, step by step: Atomic Chat as the OpenAI-compatible provider, plus permissions, plugins, and fixes for the errors we hit.
8/24/26
13 min
Best Local LLMs for 16GB RAM or VRAM in 2026
The best local LLMs for 16GB of VRAM or RAM in 2026: the quant to pick, file sizes, benchmarks, and how much context each model really leaves you.
8/23/26
12 min
What Is an MCP Server and When Do You Need One?
What an MCP server is, how the Model Context Protocol works, and how to set up, test, and securely use local and remote MCP servers in an AI app.
8/21/26
8 min
How to Run Claude Code Locally: Comprehensive Guide
Step-by-step guide to running Claude Code with a local LLM: install the agent, connect it to Atomic Chat, Ollama, llama.cpp, or LM Studio, and work offline.
8/20/26
12 min
Best Local LLM for 8GB RAM or VRAM in 2026
Compare local LLMs for 8GB RAM or VRAM, including Qwen 3.5, GLM-4.6V-Flash, Phi-4 Mini and Gemma 3, with model sizes and quantization choices.
8/19/26
12 min
Self-Hosted LLM: Models and Setup Guide
Step-by-step guide to running a self-hosted LLM with Atomic Chat: hardware requirements, the best open models of 2026, and how to expose a local API.
8/15/26
13 min
LLM KV Cache: Guide and Calculator
Learn how LLM KV cache grows with context. Estimate RAM and VRAM with our calculator and explore TurboQuant compression data.
8/8/26
10 min
How to Run DeepSeek V4 Flash Locally
DeepSeek V4 Flash needs 70–162 GB on disk. Pick the Atomic Dynamic GGUF that fits your memory, then run it locally with Atomic Chat or llama.cpp.
8/7/26
15 min
How to Run Ling 3.0 Flash Locally
Run Ling 3.0 Flash on your own machine: hardware requirements, Atomic Dynamic GGUF builds, and setup with Atomic Chat or the TurboQuant llama.cpp build.
8/6/26
10 min

How to Run GLM Locally: A Complete Guide
Run GLM locally with Atomic Chat: pick the right GLM-4.7-Flash or GLM-5.2 build for your hardware, download a GGUF, and chat entirely offline.
8/3/26
9 min
How to Run Qwen Models Locally: A Complete Guide
Learn how to run Qwen locally: pick the right model for your hardware, download the best GGUF quantization, and chat offline using Atomic Chat.
7/30/26
12 min
How to Run Kimi K3 Locally: A Complete Setup Guide
Run Kimi K3 locally: hardware requirements, Atomic Chat setup, renting 8x B300 GPUs on Vast, real costs, and the errors I hit along the way.
7/29/26
14 min
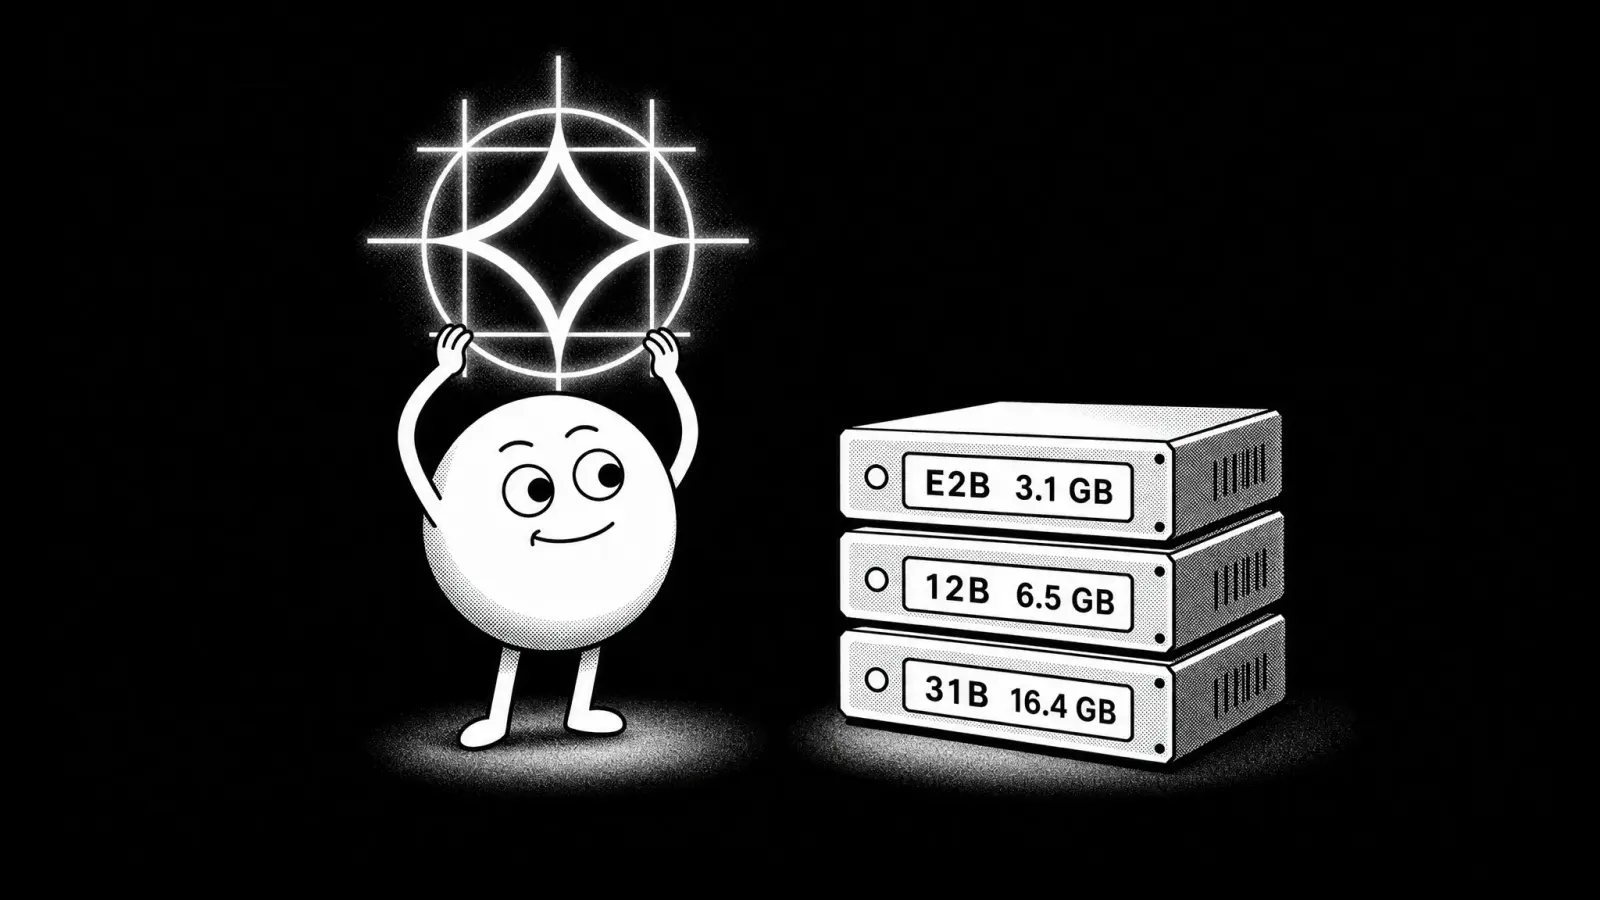
How to Run Gemma 4 Locally: a step-by-step guide
Run Google’s Gemma 4 models on your own machine. Pick the right size for your RAM or VRAM, choose a GGUF quantization, and start chatting locally.
7/28/26
8 min
38 Best MCP Connectors in 2026
38 best MCP connectors for 2026: development, documents, databases, web research, cloud, and automation — plus how to use them with local models in Atomic Chat.
8/17/26
20 min
SGLang vs vLLM: Benchmarks and Use Cases
SGLang vs vLLM compared: RadixAttention vs PagedAttention, benchmarks on unique and prefix-heavy workloads, and when to choose each engine.
8/4/26
9 min

Ollama vs vLLM: Setup and Benchmarks
Ollama vs vLLM compared: setup, model formats, concurrency, and real benchmarks — plus when each tool is the right choice for serving local LLMs.
8/2/26
12 min