Articles by author

LLM Temperature: Examples, Settings and Tests
What does LLM temperature do? Compare 900 model responses, see examples at 0, 0.7 and 1.5, and learn how to choose settings and adjust them in Atomic Chat.

9/9/26

12 min read
GPT-6 Astra Alternatives: Open-Weight and Local Models
GPT-6 Astra benchmarks and open-weight alternatives. Connect your ChatGPT subscription in Atomic Chat, or run Qwen and Laguna on your own hardware.
9/5/26
9 min
Run Qwen3.8 Flash Next Uncensored Locally
Run Qwen3.8 Flash Next uncensored locally from 80 GB up. Compare the community abliterations, pick the GGUF that fits your memory, then run it in Atomic Chat.
8/28/26
14 min
How to Run Qwen3.8 Flash Next Locally
Qwen3.8 Flash Next runs from 64 GB of RAM up with its n-gram table on SSD. Pick the Atomic Dynamic GGUF that fits, then run it with Atomic Chat or llama.cpp.
8/26/26
14 min
Run Ornith 1.5 Uncensored Locally
Ornith 1.5 uncensored runs from 6 GB up. Compare the community abliterations of the 9B and the 35B, then run one locally with Atomic Chat or llama.cpp.
8/25/26
14 min
Run Qwen 3.8 27B Uncensored Locally
Run Qwen 3.8 27B uncensored locally from 12 GB with a low-bit GGUF. Use Q4_K_M on a 24 GB GPU or 4-bit MLX on a 32 GB Mac.
8/24/26
14 min
How to Run Ornith 1.5 35B Locally
Ornith 1.5 35B runs from a 12 GB GPU up with expert offload. Pick the Atomic Dynamic GGUF that fits, then run it locally with Atomic Chat or llama.cpp.
8/20/26
15 min
How to Run Ornith 1.5 9B Locally
Ornith 1.5 9B runs from 6 GB up, 4 GB text-only. Pick the Atomic Dynamic GGUF that fits your hardware, then run it locally with Atomic Chat or llama.cpp.
8/19/26
14 min
How to Run Qwen 3.8 27B Locally
Qwen 3.8 27B runs from 12 GB up. Pick the Atomic Dynamic GGUF that fits your hardware, then run it locally with Atomic Chat or llama.cpp. Benchmarks included.
8/17/26
15 min
How to Run Hermes Agent Locally (via Atomic Chat)
Run Nous Research’s Hermes Agent locally, powered by a local model served through Atomic Chat — no cloud account and no API key. A step-by-step guide.
7/27/26
9 min
How to Run AI Agents Locally: Models and Setup
How to run AI agents locally for free: the best local models for agentic coding, hardware requirements, and a step-by-step setup guide with Atomic Chat.
7/25/26
11 min
How to Run the OpenClaw Agent Locally with Atomic Chat
Run the OpenClaw AI agent locally for free by powering it with a local model served from Atomic Chat — no cloud, no per-token bills, fully private.
7/24/26
8 min

Best Uncensored LLMs to Run Locally in 2026
Compare 10 uncensored LLMs to run locally in 2026, including Ollama builds and abliterated models, with setup advice and benchmarks.
7/17/26
15 min
What Is GGUF? A Complete Guide
Learn about GGUF, the file format for local AI models: how it works, what Q4_K_M means, and how to choose a quantization.
7/15/26
16 min

What Is Speculative Decoding?
Learn how speculative decoding accelerates LLM generation by drafting and verifying tokens, and how Atomic Chat uses it.
7/13/26
9 min
What Is NVFP4? LLM Quantization Explained
NVFP4 is a 4-bit NVIDIA format for smaller LLMs and faster inference on Blackwell GPUs. Learn how its block scaling and quantization work.
7/12/26
9 min
How to Run an LLM Locally
Learn how to run an LLM locally on your computer or Mac — pick a model for your hardware, understand quantization, and set it up in a few clicks, for free.
7/1/26
9 min
How to Run gpt-oss Locally
Run gpt-oss locally on your own machine. A step-by-step guide to gpt-oss-20b and gpt-oss-120b — the hardware you need and the fastest setup, fully offline.
7/1/26
9 min
Ollama vs llama.cpp: Speed and Setup
We benchmarked Ollama and llama.cpp with the same model and hardware. Compare speed, setup, interfaces, and see which local LLM runner fits you.
6/26/26
10 min
How to Run DeepSeek Locally
How to run DeepSeek R1 locally and offline — which distilled sizes fit your hardware, and step-by-step setup with Atomic Chat or Ollama.
6/25/26
10 min
10 Best Local LLM Apps in 2026
The 10 best local LLM apps in 2026, compared on interface, platform reach, openness, and tool support — and which one to start with.
6/23/26
12 min

Best Local LLM for Coding in 2026: A Comprehensive Guide
See how the best local LLMs for coding compare across benchmarks, which model we recommend for different use cases, and the key takeaways from our testing.
6/17/26
15 min
GGUF vs MLX on Mac: Which Format Is Faster
GGUF vs MLX on Mac: why tok/s is a misleading metric, how prefill determines real speed, and benchmarks across 5 runtimes on M1 Max and M5 Max.
6/10/26
12 min read

How to use your AI Offline: Run Local LLMs Free
Cloud AI leaks data and goes down. Offline AI runs local LLMs on your own machine. A practical guide to hardware, models, and setup that works.
5/25/26
11 min read
Is Ollama Safe? Security Audit for Your Local LLM Setup
Is Ollama safe? Review local LLM security risks and learn how to check and harden your Ollama setup.
5/21/26
12 min read

Best Local LLM for 16GB Mac in 2026
6 local LLMs that fit a 16GB Mac in 2026, with token speeds from public benchmarks, RAM usage, and a short guide to running them.
5/15/26
12 min read
8 Best LM Studio Alternatives in 2026
Compare 8 LM Studio alternatives for local AI in 2026, including Atomic Chat, Ollama and llama.cpp, by features and use case.
7/25/26
12 min
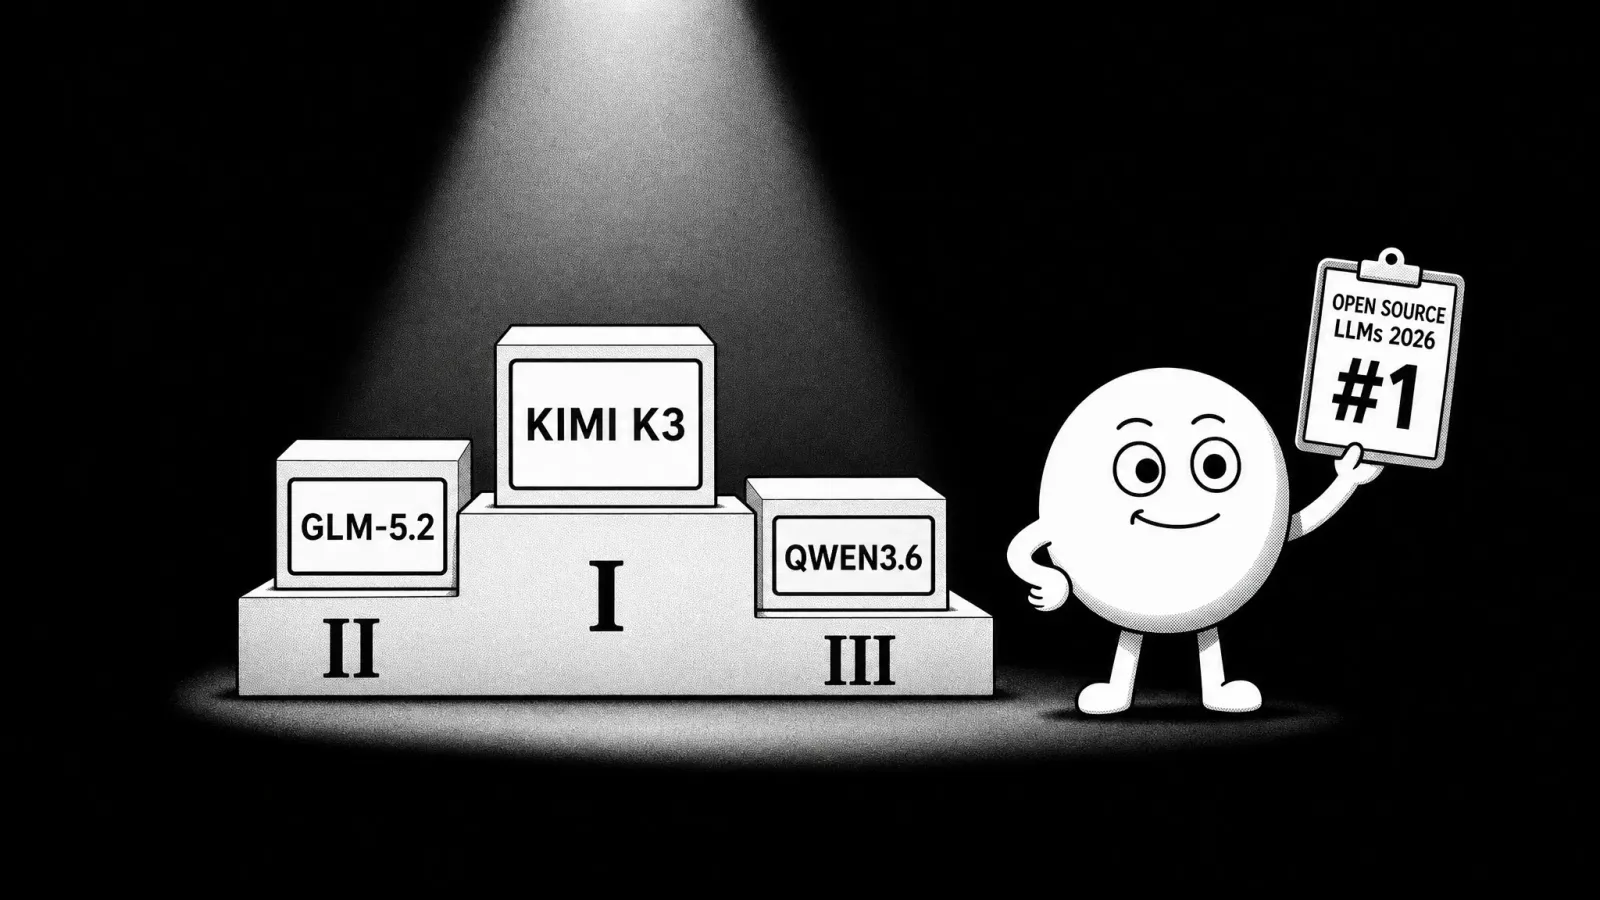
Best Open Source LLM in 2026: 10 Models Ranked
Compare 10 open source LLMs for 2026, including Qwen3.6, GLM-5.2, Kimi K3 and DeepSeek-V4, with benchmarks, licenses and hardware needs.
7/21/26
16 min
6 Offline AI Apps for iPhone and Android (2026)
Which offline AI app actually works on your phone? Six apps compared by speed, RAM, and privacy — with device benchmarks and honest recommendations.
6/9/26
8 min read
Self-Hosted LLM on Mac: 2026 Benchmarks
We tested five local LLMs on Apple Silicon. Compare coding results, measured token speeds, hardware requirements and model choices for 2026.
6/8/26
8 min read
Best LLM for Coding: Cloud and Open Source (2026)
Which coding LLM is worth it in 2026? Claude Sonnet leads SWE-bench at 79.6%. Qwen3-Coder runs locally. Benchmarks, pricing, and hardware compared.
6/5/26
6 min read
Ollama vs LM Studio (2026): Which Should You Use?
Ollama vs LM Studio in 2026: features, real Mac benchmarks, hardware requirements, APIs, and pricing compared — plus a plain guide to choosing the right one.
6/4/26
11 min read
10 Best Ollama Alternatives in 2026
The best Ollama alternatives in 2026 — Atomic Chat, LM Studio, Jan, GPT4All, vLLM and more. Compare GUI, mobile, open-source and local-API support.
6/4/26
7 min read
Qwen 3.7-Plus vs MiniMax M3: Best New LLM for Coding
We tested Qwen 3.7-Plus and MiniMax M3 for coding. Compare benchmarks, a landing page build, and recommendations for five coding tasks.
6/2/26
6 min read
ChatGPT Free for Students in 2026: What Still Works
There is no ChatGPT student discount anymore. Here is what is actually free for students in 2026, including local AI that runs offline with no limits.
5/26/26
8 min read